Fine-tuning vs. RAG: Financial Q&A Showdown
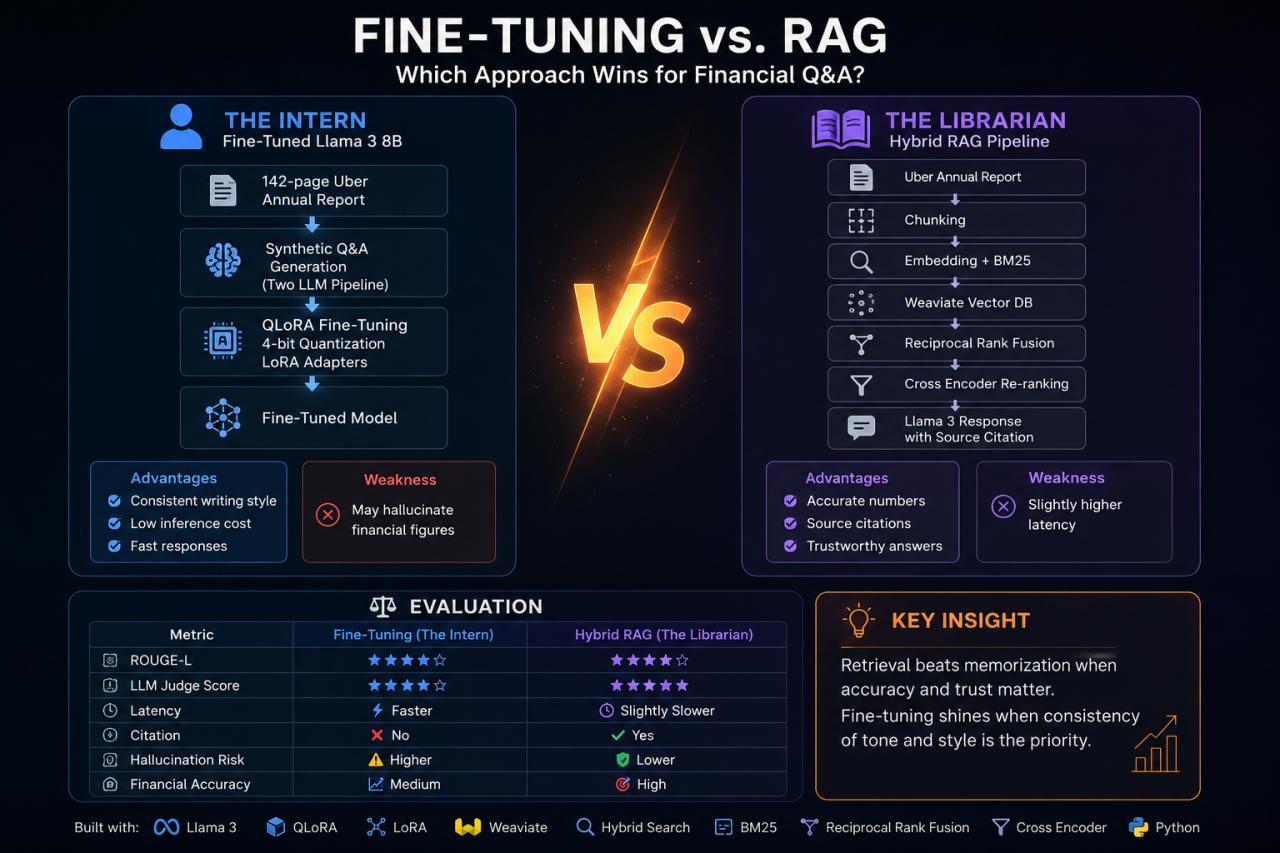
Two end-to-end architectures for question answering over Uber’s 2024 Annual Report (a 142-page 10-K), built and compared head to head.
Technical implementation
- Fine-tuned Qwen2.5-3B-Instruct using QLoRA with 4-bit quantization and LoRA adapters.
- Created synthetic training data using a dual-LLM pipeline.
- Built a hybrid RAG architecture in Weaviate combining dense vector search and BM25.
- Merged results with Reciprocal Rank Fusion and applied cross-encoder reranking.
- Evaluated with ROUGE-L, LLM-as-a-Judge, faithfulness, accuracy, latency, and cost projections.
Pipeline (illustrative diagram)
10-K reportthenChunkingthenDense + BM25thenRank fusionthenCross-encoder rerankthenLLM answer
Key finding
RAG delivered stronger factual accuracy and source citation, while fine-tuning performed better in tone and stylistic consistency.